Serving LLMs on Kubernetes: GPUs, vLLM and Autoscaling
A practical guide to self-hosting models on Kubernetes — GPU nodes, model servers, cold starts, autoscaling and smart routing.
Key takeaways
- Kubernetes has become the standard control plane for self-hosted AI inference, but GPUs need extra components: drivers, the device plugin and monitoring.
- The NVIDIA GPU Operator automates the GPU software stack on each node.
- A model server such as vLLM runs as a Deployment exposing an OpenAI-compatible API; startup probes and model caching handle slow cold starts.
- Autoscale on inference signals — queue depth, KV-cache usage — not CPU utilization.
- Model-aware routing (Gateway API Inference Extension, llm-d) improves cache hits and latency at scale.
Calling a hosted model API is the fastest way to ship an AI feature. But many organizations also run models themselves — open-weight models for cost, data residency, customization or latency. When they do, the platform of choice is almost always Kubernetes. This guide walks through what it takes to serve LLMs on Kubernetes well, from GPU nodes to autoscaling.
The reference architecture
Step 1 — GPU nodes and the GPU Operator
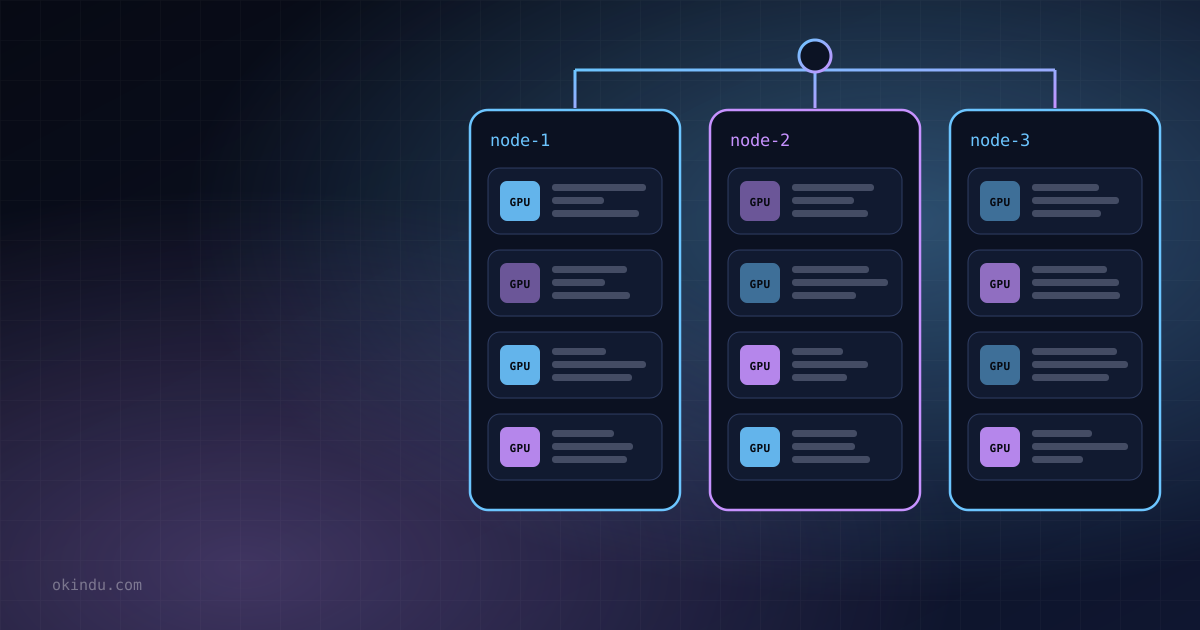
Kubernetes doesn't understand GPUs natively. A node needs the NVIDIA driver, the container toolkit (so containers can access the GPU) and the device plugin, which advertises GPUs to the scheduler as an extended resource called nvidia.com/gpu.
The NVIDIA GPU Operator installs and manages all of this as Kubernetes workloads: drivers, toolkit, device plugin, GPU Feature Discovery (which labels nodes with GPU model and memory), the DCGM exporter for metrics, and the MIG manager. Managed services such as Amazon EKS, Google GKE and Azure AKS offer GPU-optimized node images that handle part of this for you.
Best practices for GPU node pools:
- Taint GPU nodes (e.g.,
nvidia.com/gpu=present:NoSchedule) so only workloads that tolerate the taint — your model servers — land on expensive hardware. - Separate pools by GPU type and select with node labels; a 70B model and an embedding model have very different needs.
- Use node autoscaling (Karpenter on EKS, cluster autoscaler or node auto-provisioning elsewhere) to add GPU nodes on demand — and remove them when idle.
Step 2 — Deploy a model server
vLLM is the most common open-source choice: it implements continuous batching, PagedAttention, prefix caching and quantization, and exposes an OpenAI-compatible HTTP API. Here's a production-shaped Deployment for a 7B-class model on one GPU:
apiVersion: apps/v1
kind: Deployment
metadata:
name: llm-server
labels: {app: llm-server}
spec:
replicas: 2
selector:
matchLabels: {app: llm-server}
template:
metadata:
labels: {app: llm-server}
spec:
tolerations:
- key: nvidia.com/gpu
operator: Exists
effect: NoSchedule
containers:
- name: vllm
image: vllm/vllm-openai:latest # pin an exact version tag in production
command: ["vllm", "serve"]
args:
- "Qwen/Qwen2.5-7B-Instruct"
- "--max-model-len=32768"
- "--gpu-memory-utilization=0.90"
- "--enable-prefix-caching"
ports:
- containerPort: 8000
env:
- name: HF_TOKEN # only needed for gated models
valueFrom: {secretKeyRef: {name: hf-token, key: token}}
resources:
limits:
nvidia.com/gpu: 1
memory: 48Gi
volumeMounts:
- {name: model-cache, mountPath: /root/.cache/huggingface}
- {name: shm, mountPath: /dev/shm}
startupProbe: # model download + load can take minutes
httpGet: {path: /health, port: 8000}
periodSeconds: 10
failureThreshold: 90
readinessProbe:
httpGet: {path: /health, port: 8000}
periodSeconds: 5
volumes:
- name: model-cache
persistentVolumeClaim: {claimName: model-cache}
- name: shm # shared memory for multi-GPU communication
emptyDir: {medium: Memory, sizeLimit: 16Gi}
---
apiVersion: v1
kind: Service
metadata:
name: llm-server
spec:
selector: {app: llm-server}
ports:
- port: 80
targetPort: 8000Applications can now call http://llm-server/v1/chat/completions with any OpenAI-compatible client. For larger models, request multiple GPUs per pod and add --tensor-parallel-size; for models too large for one node, use multi-node serving patterns such as LeaderWorkerSet or Ray.
Step 3 — Tame cold starts
LLM pods are slow to start: pulling a multi-gigabyte image, downloading tens or hundreds of gigabytes of weights, loading them into GPU memory and compiling kernels. A pod that takes ten minutes to become ready makes autoscaling sluggish. Mitigations:
- Cache weights on a shared volume, local NVMe or a pre-populated PVC rather than downloading from the internet on every start.
- Stream weights directly from object storage into GPU memory using loaders designed for it.
- Pre-pull images to GPU nodes and keep images lean.
- Keep warm capacity — a minimum replica count sized for baseline traffic.
- Use startup probes with generous thresholds so Kubernetes doesn't kill pods that are still loading.
Step 4 — Autoscale on the right signal
CPU utilization is meaningless for GPU inference. Scale on signals that reflect inference load. vLLM exposes Prometheus metrics such as the number of waiting requests and KV-cache usage. With KEDA, you can scale directly on a PromQL query:
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
metadata:
name: llm-server
spec:
scaleTargetRef:
name: llm-server
minReplicaCount: 1
maxReplicaCount: 8
cooldownPeriod: 600 # scale down slowly: new pods are expensive to start
triggers:
- type: prometheus
metadata:
serverAddress: http://prometheus.monitoring.svc:9090
query: sum(vllm:num_requests_waiting)
threshold: "10"Pod autoscaling and node autoscaling work together: KEDA adds replicas, the pending pods trigger the node autoscaler to provision GPU nodes, and scale-down returns them when traffic drops. Scale-to-zero is possible for dev or batch workloads, but cold starts make it a poor fit for interactive traffic.
Step 5 — Route requests intelligently
A standard round-robin load balancer treats every request and every pod as identical. LLM serving isn't like that: requests vary wildly in length, and a pod that already holds a conversation's prefix in its KV cache can answer much faster. Newer components address this:
- Gateway API Inference Extension — a Kubernetes SIG project that adds model-aware routing to Gateway API implementations, picking endpoints based on queue length, KV-cache utilization and LoRA adapters loaded.
- llm-d — an open-source project launched in 2025 by Red Hat, Google, IBM, NVIDIA, CoreWeave and others, combining vLLM with cache-aware routing and prefill/decode disaggregation on Kubernetes.
- NVIDIA Dynamo — a distributed inference framework with KV-cache-aware routing and disaggregated serving across engines.
- KServe — an open-source project providing an
InferenceServiceabstraction, with LLM runtimes, autoscaling and canary rollouts built in.
Sharing GPUs
Not every model needs a whole GPU. Small embedding, reranking or classification models can share:
| Method | Isolation | Use when |
|---|---|---|
| MIG (Multi-Instance GPU) | Hardware partitions with dedicated memory and compute (up to 7 per A100/H100-class GPU) | Predictable performance for multiple small models |
| Time-slicing | None — processes take turns | Dev/test, bursty low-priority workloads |
| MPS | Partial — concurrent kernels | Many small inference processes |
| One server, many models | Application-level | Multiple LoRA adapters on a shared base model |
Production checklist
- Pin image and model versions; roll out changes with canaries.
- Set request limits (max tokens, max concurrent requests) to protect latency for everyone.
- Put authentication, rate limiting and usage accounting in the gateway.
- Export GPU metrics (DCGM) and server metrics to Prometheus; alert on queue growth and error rates.
- Use PodDisruptionBudgets so node upgrades don't take all replicas down at once.
- Track cost per million tokens served — and compare against hosted APIs honestly.